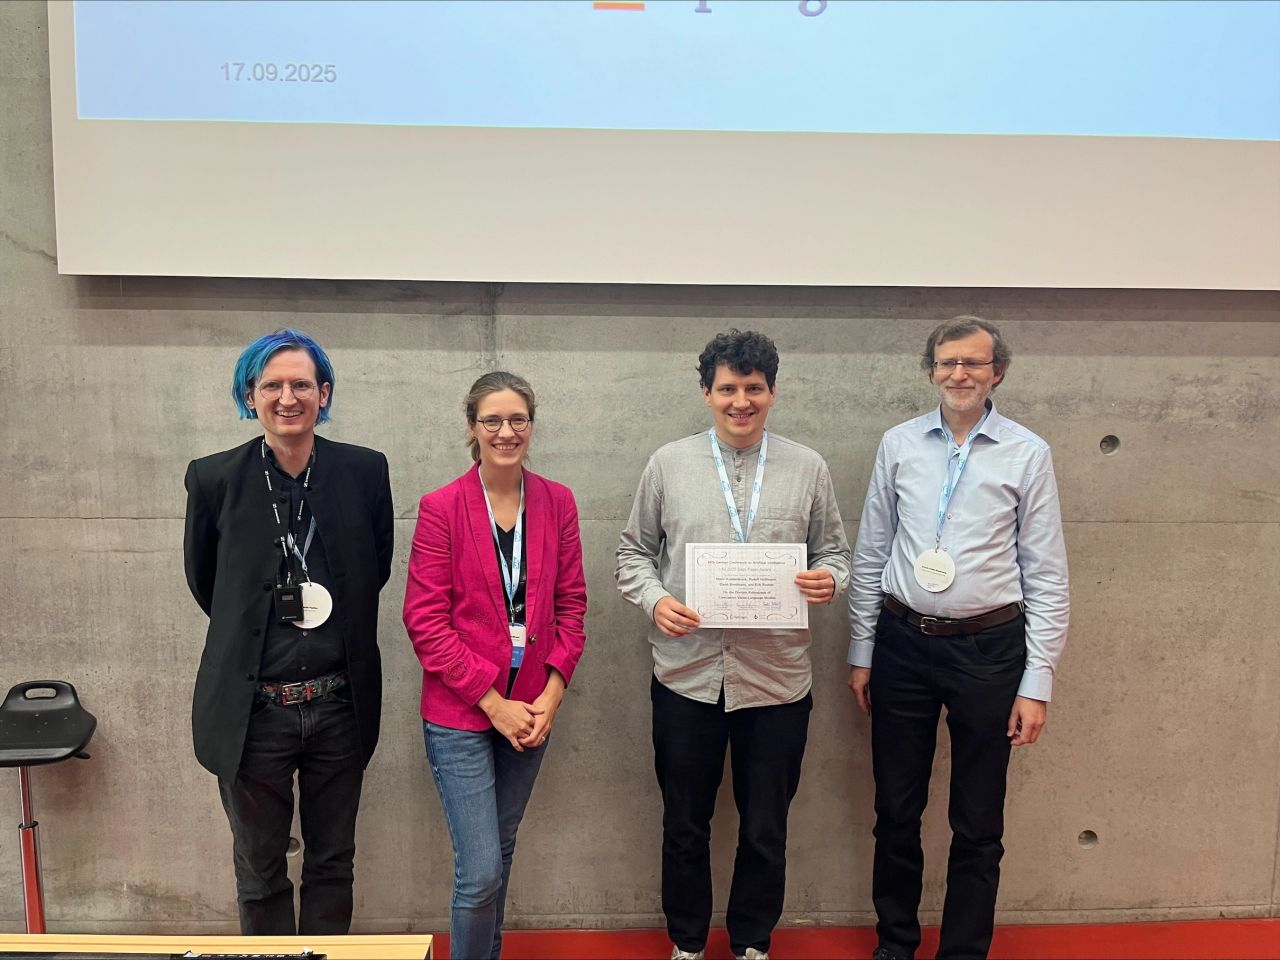
17.09.2025
Our paper On the Domain Robustness of Contrastive Vision-Language Models by Mario Koddenbrock, Rudolf Hoffmann, David Brodmann and Erik Rodner received the Best Paper Award at KI 2025, the 48th German Conference on Artificial Intelligence of the Gesellschaft für Informatik.
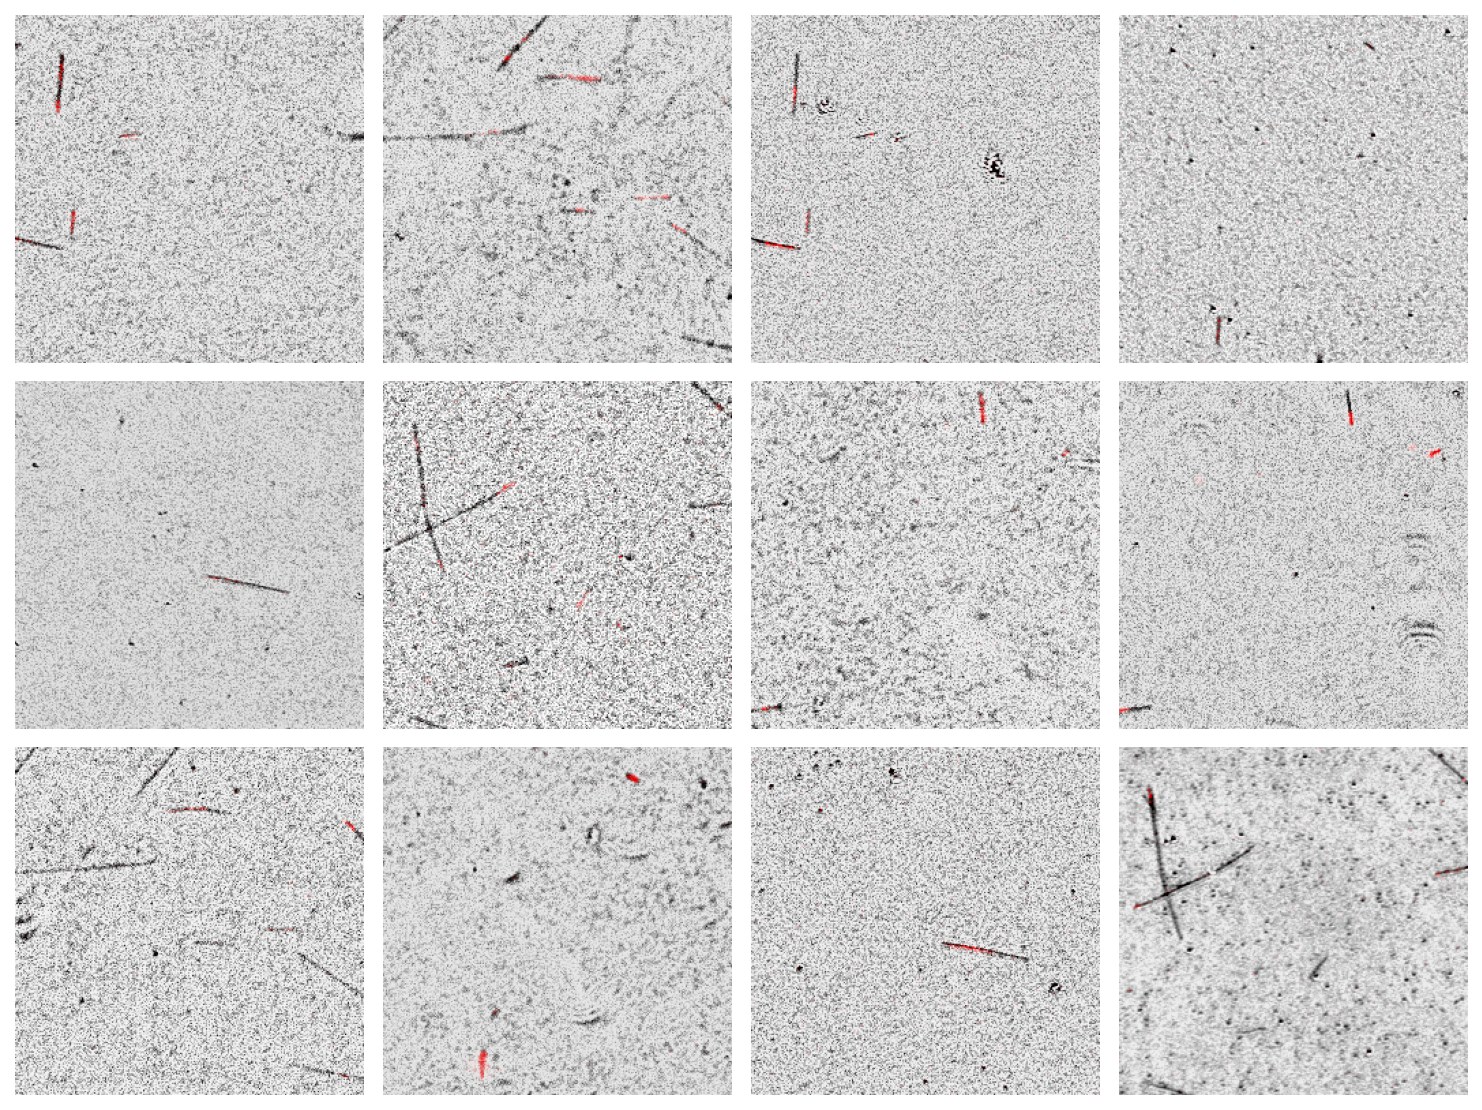
Foundation models such as CLIP do well on general benchmarks, but they can fail under the conditions of a specific application, such as unusual lighting or imaging conditions. The paper introduces DeepBench, a framework that uses a large language model to generate realistic image corruptions for a given application domain, without labeled data. Across six real-world domains, the robustness of contrastive vision-language models varies widely, which shows that models should be evaluated for the domain they are deployed in.
DeepBench is open source.