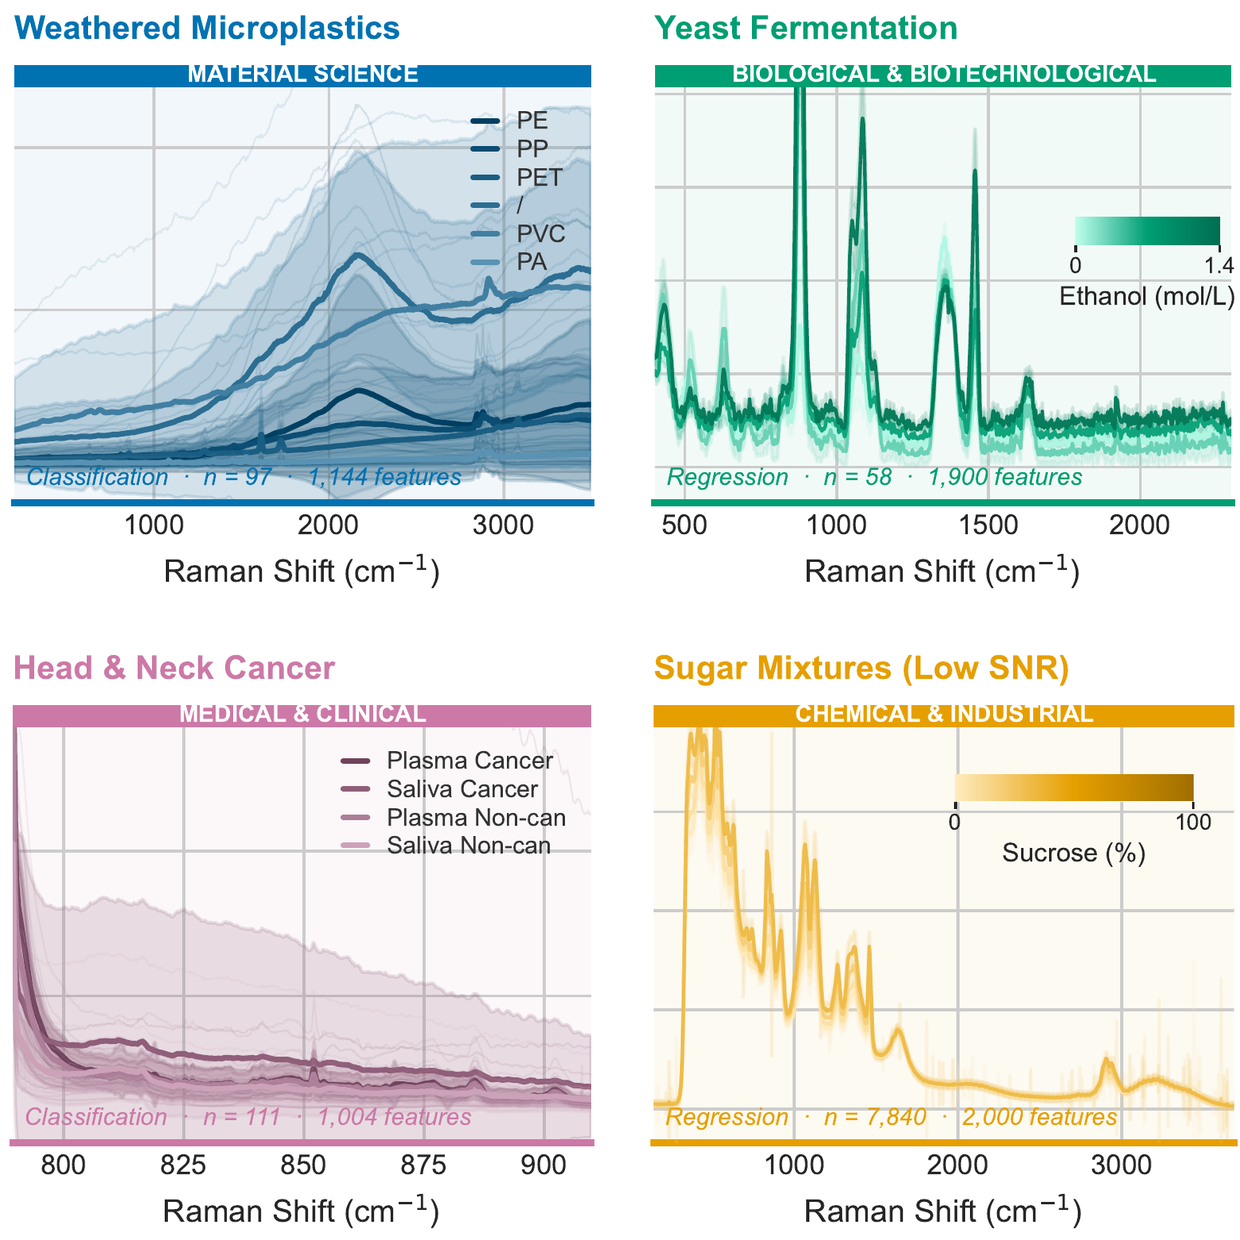
Public Raman datasets are scattered across Kaggle, Hugging Face, Zenodo, Figshare, Mendeley, GitHub and other archives, each in its own format. raman-data puts them behind one function: it lists the datasets, downloads one, and loads it as NumPy arrays of spectra, Raman shifts and targets.
It currently covers 93 datasets for classification, regression, denoising and super-resolution, which can be filtered by task and by application domain (medical, biological, chemical, material science). A curated subset is used for the RamanBench leaderboard.
from raman_data import raman_data, TASK_TYPE

raman_data(task_type=TASK_TYPE.Classification)   # list datasets
dataset = raman_data("bioprocess_substrates")     # load one
X, y = dataset.spectra, dataset.targets
Install it with pip install raman-data.