This research addresses the critical challenge of maintaining data quality in machine learning pipelines by analyzing how realistic errors manifest, propagate, and can be mitigated in tabular datasets.
The initiative delivered advancements across three interconnected phases:
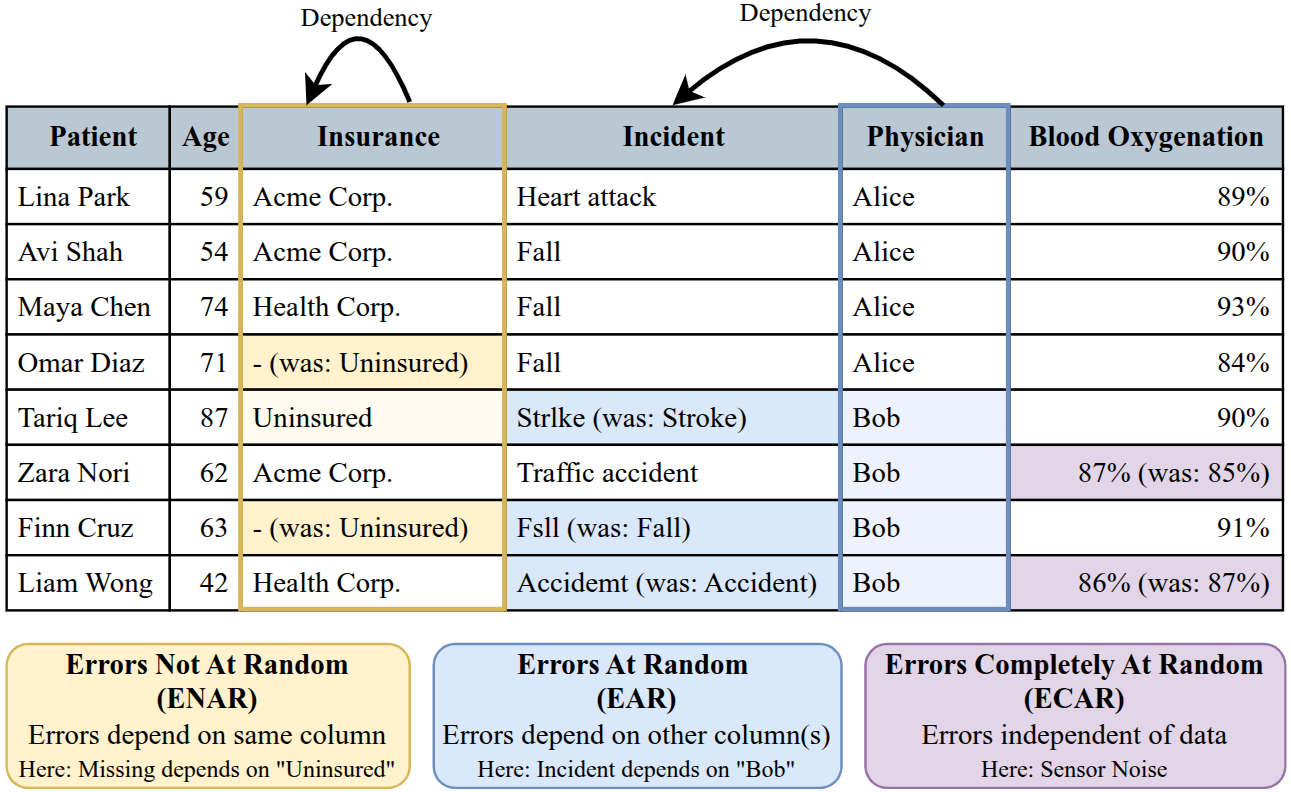
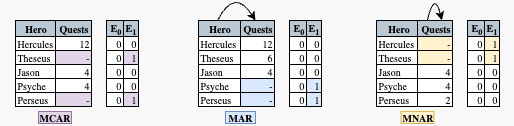
- **Error Modeling:** Simulating and modeling realistic data corruptions in tabular structures using the `tab_err` framework.
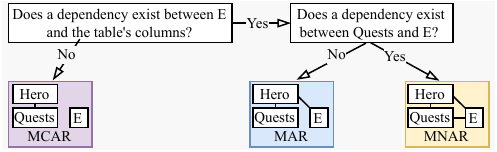
- **Error Diagnosis:** Developing automated methods (MechDetect) to infer the underlying statistical mechanisms that cause data corruptions, determining whether errors depend on the dataset's distribution itself.
- **Automated Cleaning:** Implementing application-agnostic pipelines (Conformal Data Cleaning) that combine imputation with conformal prediction to systematically detect and repair erroneous values without relying on manual heuristics.
Users can interact with these frameworks and explore the software capabilities via our live demonstration.